Tables for Clinical Reports
The output end of a clinical submission is tables, listings and graphs, and the
tables are the conservative part: same shells decade after decade, one row per
characteristic, one column per arm, counts and percentages with the denominators
shown. Two Roche packages build them. rtables is the engine: you declare a layout
as a tree of row and column splits and analysis steps, and the layout is then applied
to data. tern is the clinical layer on top: it knows what a demographics table’s
rows actually are, so analyze_vars on AGE and SEX produces the n, mean (SD),
median, range and count-with-percent rows a regulator expects, instead of a bare
mean.
Both run on ADaM data, not SDTM, because the analysis population and the arm labels
are already settled there. This page reads the reference adsl and adae from
pharmaverseadam, the datasets the previous
page reproduced.
library(rtables)library(tern)library(dplyr)library(pharmaverseadam)
data(adsl)
arms <- c("Placebo", "Xanomeline Low Dose", "Xanomeline High Dose")
# Tables want factors: the level set must be the same under every arm,# which character columns converted on the fly cannot guarantee.adsl <- adsl %>%  filter(SAFFL == "Y") %>%  mutate(    ACTARM = factor(ACTARM, levels = arms),    SEX = factor(SEX),    RACE = factor(RACE)  )
A demographics table in rtables
Section titled “A demographics table in rtables”The layout is the program. split_cols_by declares one column per arm,
add_colcounts puts the arm sizes into the header, and analyze applies a
statistic to a variable within each cell of the split. Nothing is computed until
build_table meets the data, and the same layout would run unchanged on another
study’s ADSL.
tbl <- basic_table(  title = "Table 14-1.1",  subtitles = "Demographics and Baseline Characteristics, Safety Population") %>%  split_cols_by("ACTARM") %>%  add_colcounts() %>%  analyze("AGE") %>%  build_table(adsl)
tbl
Table 14-1.1Demographics and Baseline Characteristics, Safety Population
——————————————————————————————————————————————————————————— Placebo Xanomeline Low Dose Xanomeline High Dose (N=86) (N=96) (N=72)———————————————————————————————————————————————————————————Mean 75.21 75.96 73.78The same table, the clinical version, with tern
Section titled “The same table, the clinical version, with tern”rtables’ analyze gives one statistic per call. tern’s analyze_vars gives the
standard set in one step, and it types the variable for you: a numeric gets n, mean
(SD), median and range, a factor gets counts with percentages. The percentages come
from the cell counts in the header, which is why add_colcounts stays in the
layout.
tbl <- basic_table() %>%  split_cols_by("ACTARM") %>%  add_colcounts() %>%  analyze_vars(vars = c("AGE", "SEX", "RACE")) %>%  build_table(adsl)
tbl
Placebo Xanomeline Low Dose Xanomeline High Dose (N=86) (N=96) (N=72)—————————————————————————————————————————————————————————————————————————————————————————————AGE n 86 96 72 Mean (SD) 75.2 (8.6) 76.0 (8.1) 73.8 (7.9) Median 76.0 78.0 75.5 Min - Max 52.0 - 89.0 51.0 - 88.0 56.0 - 88.0SEX n 86 96 72 F 53 (61.6%) 55 (57.3%) 35 (48.6%) M 33 (38.4%) 41 (42.7%) 37 (51.4%)RACE n 86 96 72 AMERICAN INDIAN OR ALASKA NATIVE 0 0 1 (1.4%) BLACK OR AFRICAN AMERICAN 8 (9.3%) 6 (6.2%) 9 (12.5%) WHITE 78 (90.7%) 90 (93.8%) 62 (86.1%)An adverse event table with the right denominators
Section titled “An adverse event table with the right denominators”The AE summary has one trap: the analysis dataset is long, one row per event, and a
subject with five events appears five times. The count the table must show is
subjects with at least one event, and the percentage must divide by the subjects at
risk, not by rows. Two pieces of the call handle that: count_occurrences counts
subjects, and alt_counts_df hands the layout the ADSL arm sizes as the
denominators. Here also is the treatment-emergent flag, the ADaM column that keeps
pre-treatment events out of the summary.
data(adae)
adae_em <- adae %>%  filter(SAFFL == "Y", TRTEMFL == "Y") %>%  mutate(ACTARM = factor(ACTARM, levels = arms))
tbl_ae <- basic_table() %>%  split_cols_by("ACTARM") %>%  add_colcounts() %>%  count_occurrences(vars = "AEDECOD") %>%  build_table(adae_em, alt_counts_df = adsl)
# The full table runs one row per coded term. Print its first rows.head(tbl_ae, 10)cat("coded terms in the full table:", nrow(tbl_ae), "\n")
Placebo Xanomeline Low Dose Xanomeline High Dose (N=86) (N=96) (N=72)———————————————————————————————————————————————————————————————————————————————————————ABDOMINAL DISCOMFORT 0 0 1 (1.4%)ABDOMINAL PAIN 1 (1.2%) 3 (3.1%) 1 (1.4%)ACROCHORDON EXCISION 0 0 1 (1.4%)ACTINIC KERATOSIS 0 0 1 (1.4%)AGITATION 2 (2.3%) 3 (3.1%) 0ALCOHOL USE 0 0 1 (1.4%)ALLERGIC GRANULOMATOUS ANGIITIS 0 0 1 (1.4%)ALOPECIA 1 (1.2%) 0 0AMNESIA 0 0 1 (1.4%)ANXIETY 0 3 (3.1%) 0coded terms in the full table: 230GSK’s piece: separating computation from display with tfrmt
Section titled “GSK’s piece: separating computation from display with tfrmt”rtables computes and formats in one step. GSK’s tfrmt takes the opposite position:
the analysis program emits a long, machine-readable results table, an ARD, and a
separate display specification formats it. The same ARD can then feed an RTF, an
HTML table or a figure without recomputing. The ARD here is the AE summary computed
directly, one row per term per arm per statistic.
top_terms <- adae_em %>%  count(AEDECOD, sort = TRUE) %>%  slice_head(n = 4) %>%  pull(AEDECOD)
denom <- adsl %>% count(ACTARM, name = "N")
ard <- adae_em %>%  filter(AEDECOD %in% top_terms) %>%  distinct(USUBJID, AEDECOD, ACTARM) %>%  count(AEDECOD, ACTARM, name = "n") %>%  left_join(denom, by = "ACTARM") %>%  mutate(pct = 100 * n / N) %>%  select(AEDECOD, ACTARM, n, pct) %>%  tidyr::pivot_longer(    cols = c("n", "pct"), names_to = "param", values_to = "value"  ) %>%  mutate(label = AEDECOD, column = ACTARM) %>%  select(label, param, column, value)
as.data.frame(ard)
label param column value1 APPLICATION SITE ERYTHEMA n Placebo 3.0000002 APPLICATION SITE ERYTHEMA pct Placebo 3.4883723 APPLICATION SITE ERYTHEMA n Xanomeline Low Dose 13.0000004 APPLICATION SITE ERYTHEMA pct Xanomeline Low Dose 13.5416675 APPLICATION SITE ERYTHEMA n Xanomeline High Dose 14.0000006 APPLICATION SITE ERYTHEMA pct Xanomeline High Dose 19.4444447 APPLICATION SITE PRURITUS n Placebo 6.0000008 APPLICATION SITE PRURITUS pct Placebo 6.9767449 APPLICATION SITE PRURITUS n Xanomeline Low Dose 23.00000010 APPLICATION SITE PRURITUS pct Xanomeline Low Dose 23.95833311 APPLICATION SITE PRURITUS n Xanomeline High Dose 21.00000012 APPLICATION SITE PRURITUS pct Xanomeline High Dose 29.16666713 ERYTHEMA n Placebo 8.00000014 ERYTHEMA pct Placebo 9.30232615 ERYTHEMA n Xanomeline Low Dose 14.00000016 ERYTHEMA pct Xanomeline Low Dose 14.58333317 ERYTHEMA n Xanomeline High Dose 14.00000018 ERYTHEMA pct Xanomeline High Dose 19.44444419 PRURITUS n Placebo 8.00000020 PRURITUS pct Placebo 9.30232621 PRURITUS n Xanomeline Low Dose 21.00000022 PRURITUS pct Xanomeline Low Dose 21.87500023 PRURITUS n Xanomeline High Dose 25.00000024 PRURITUS pct Xanomeline High Dose 34.722222The tfrmt specification then says, declaratively, which ARD columns play which
display role and how the values render. frmt_combine("{n} ({pct}%)") is the
familiar n (x.x%) display, defined once and applied everywhere.
library(tfrmt)library(ggplot2)
ae_tfrmt <- tfrmt(  label = "label",  param = "param",  column = "column",  value = "value",  body_plan = body_plan(    frmt_structure(      group_val = ".default", label_val = ".default",      frmt_combine("{n} ({pct}%)", n = frmt("xx"), pct = frmt("xx.x"))    )  ))
# gt renders to HTML; print_to_ggplot renders the same display as a figure,# which is the form this page can embed.p <- print_to_ggplot(ae_tfrmt, ard)ggsave("outputs/tfrmt-ae.png", plot = p, width = 8, height = 2.5, dpi = 150)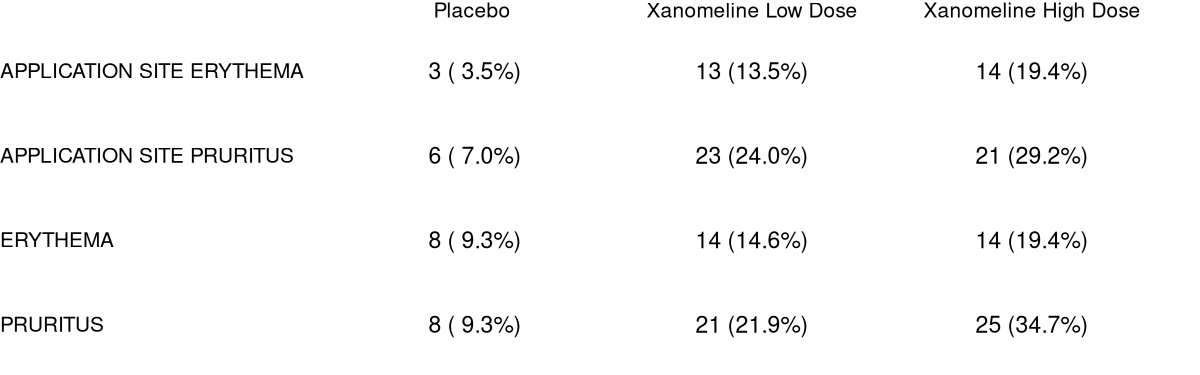
The rendered values, the ARD above them and the tern table carry the same four
terms, the same counts and the same denominators. The dose gradient is the finding a
reviewer looks for: application-site reactions rise with the xanomeline dose, which
is the known pharmacology of a transdermal patch. The computation happened once, in
the ARD, and the display layer added nothing but format. That
separation is the design GSK is pushing on the industry, and the metadata packages
metacore and metatools, built with Atorus, apply the same idea to dataset
specifications.
The rest of the TLG vocabulary
Section titled “The rest of the TLG vocabulary”chevron packages whole standard outputs as templates on top of rtables and
tern, rlistings covers listings, and teal turns the same ADaM data into
exploratory Shiny apps. tfrmtbuilder is a Shiny app for writing a tfrmt
specification interactively, and docorator handles the page furniture, headers,
footers and file formats, around a finished display. None of them needs new
concepts: each is the layout model or the ARD split at a larger scale.